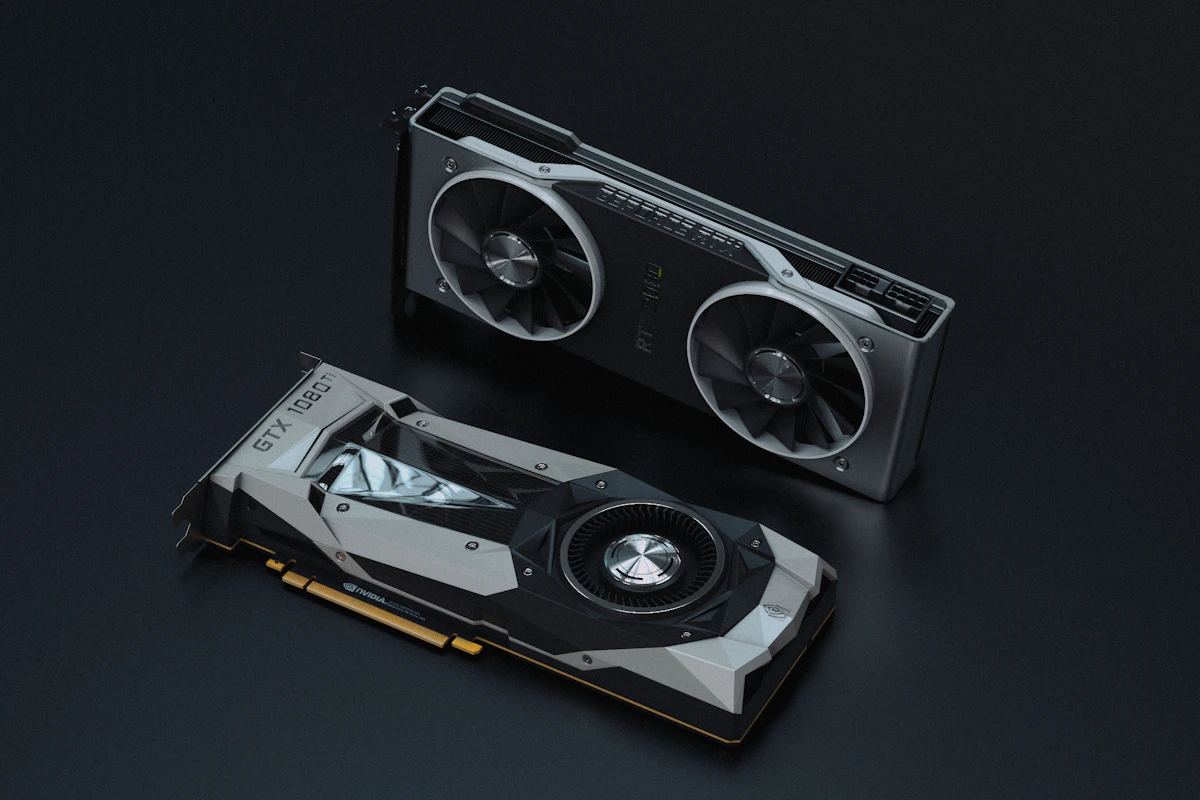
NVIDIA RTX 5090 Blackwell vs RTX 4090: Local AI Benchmark
Enterprise developers hosting local LLMs (Ollama, vLLM, TensorRT-LLM) require immense GPU VRAM bandwidth and FP8/FP4 low-precision Tensor calculation speed.
---
🚀 Architectural Breakthroughs
- Memory Interface: 512-bit GDDR7 at 1,792 GB/s bandwidth (RTX 5090) vs 384-bit GDDR6X at 1,008 GB/s (RTX 4090).
- VRAM Capacity: 32GB GDDR7 vs 24GB GDDR6X.
- Tokens Per Second (Llama 3 70B Q4_K_M):
- RTX 5090 (32GB): 68.4 tok/sec (Fits full model weights in VRAM without offloading)
- RTX 4090 (24GB): 28.1 tok/sec (Requires CPU system RAM offloading for 70B parameters)